How PAI Works
PAI is a compact, whisper-quiet neural workstation that lives on your shelf. Your phones, laptops, and tablets connect to it over a private WireGuard mesh. Models, personal memory, and agent orchestration run entirely on bare metal inside your home.
The Physical Perimeter Model
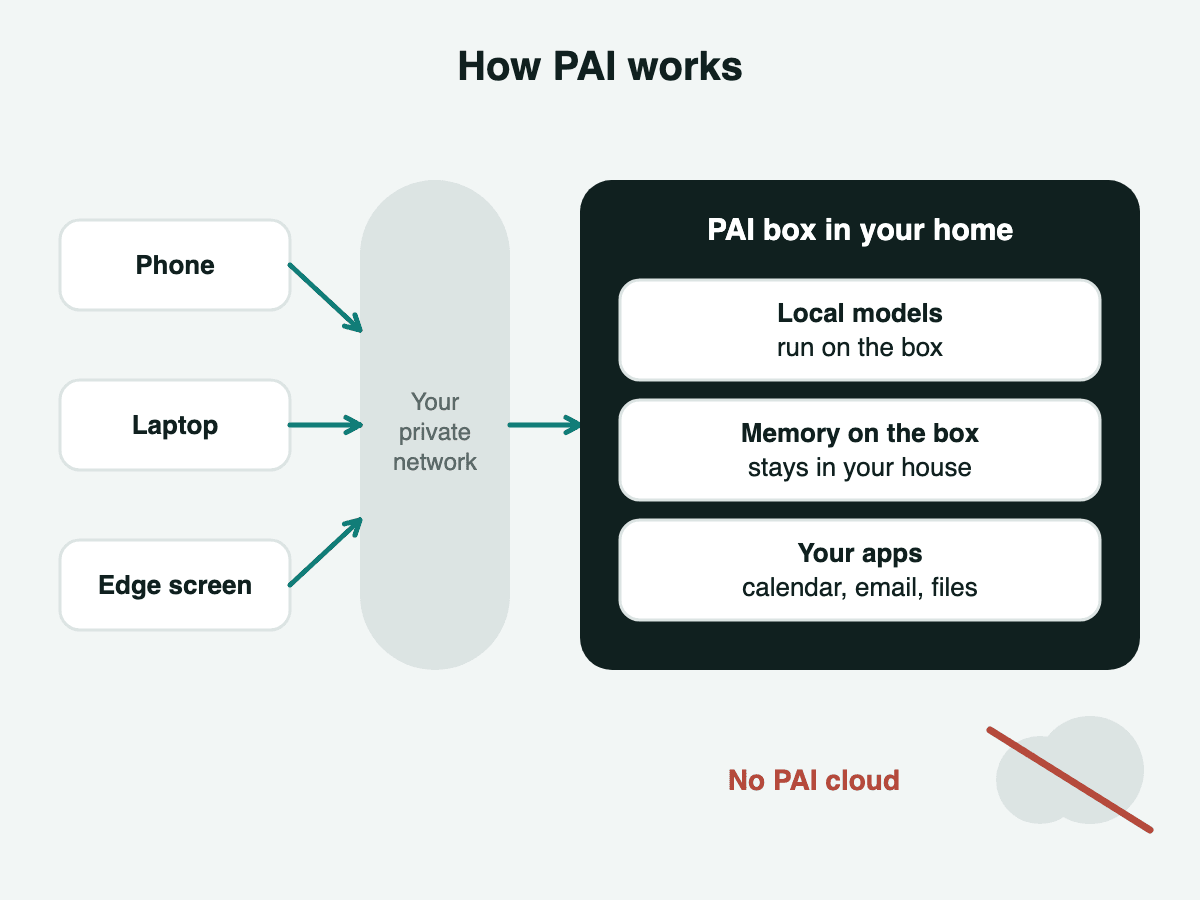
Every query you submit to a cloud AI model crosses third-party networks, lingers in remote caches, and feeds multitenant training data. PAI flips this topology: compute moves to your data, rather than streaming your life to remote datacenters.
Two Doors, One Rule
Traditional home servers require port-forwarding, dynamic DNS, and exposure to automated port scanners. PAI replaces this fragility with a mathematically enforced dual-boundary network architecture.
Direct WireGuard Peer Mesh
Your phones, laptops, and tablets connect directly to PAI through a WireGuard overlay network (Tailscale or self-hosted Headscale) tagged tag:pai-box.
- Zero Inbound Ports: Your router opens zero public WAN ports. UPnP and NAT-PMP are disabled at kernel level.
- 127.0.0.1 Loopback Binding: The admin UI and inference endpoints bind strictly to localhost and WireGuard interfaces.
- Mutual TLS Authentication: Every interaction requires verified ed25519 cryptographic key exchange.
Edge-Sealed Ciphertext Pipe
Webhooks, incoming emails, and messaging bots arrive over an outbound-initiated tunnel (cloudflared). The Cloudflare edge holds only your public key ($K_{pub}$).
- Asymmetric Ingress Sealing: Payloads are encrypted with X25519 at the edge before crossing the tunnel boundary.
- Zero Cloud Decryption: Cloudflare sees only opaque ciphertext. The private key ($K_{priv}$) never leaves your hardware.
- Human-in-the-Loop Confirmation: Outbound replies drafted by local agents require explicit user approval.
No unencrypted data ever resides on a third-party server.
Third parties carry only end-to-end ciphertext envelopes or ephemeral transport packets. Your personal conversations, documents, vector embeddings, and model weights live exclusively inside your physical box.
Sovereign AI Interfaces
PAI OS boots into native sovereign interfaces: Hermes UI for natural voice, chat, and memory exploration, First-Boot Setup for local onboarding, and Rakazo UI for autonomous browser automation.
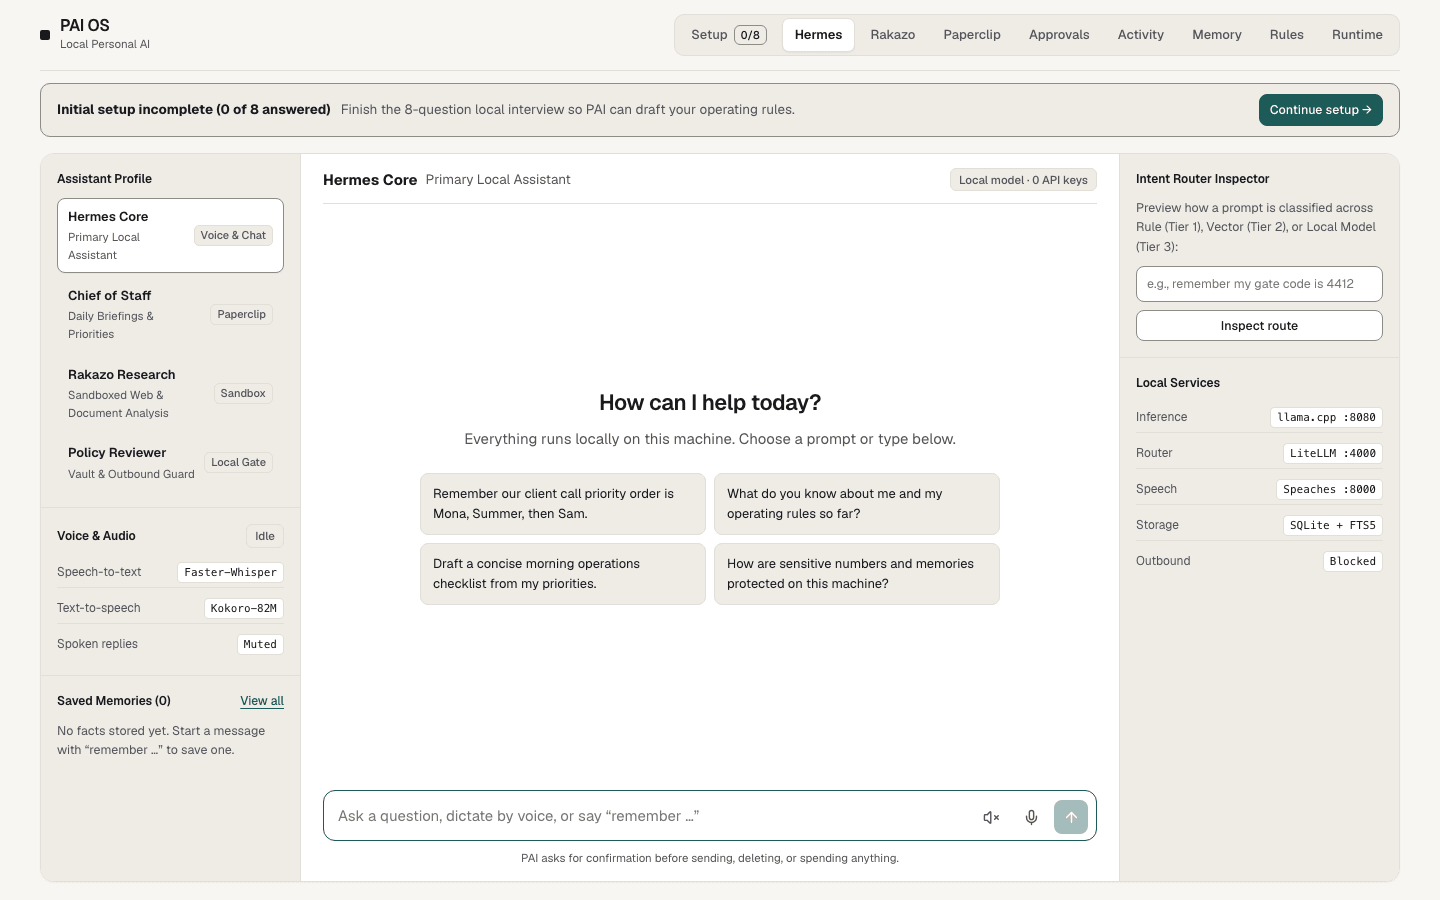
Streaming Silero VAD turn detection with instant barge-in interruption. Natural voice-to-voice conversation.
Single-file deterministic vector index. Search conversations, notes, and local documents with zero cloud sync.
Real-time token speed counter, unified memory allocation gauges, and temperature monitoring on bare metal.
Sub-500ms Real-Time Voice Architecture
Built on the LiveKit Agents SDK and WebRTC real-time media transport. Engineered for sub-500ms conversational turn-taking with instant barge-in interruption and offline local fallback.
VAD & Ingest
Silero VAD runs client-side frame-by-frame with WebRTC echo cancellation and adaptive noise reduction.
Streaming STT
Zero-latency streaming transcription. Local Whisper or Deepgram streaming emits partials every 80ms.
Local TTFT
llama.cpp and Ollama stream first token (TTFT) directly into synthesis buffer with speculative decoding.
Streaming TTS
Sentence-chunked audio synthesis via Kokoro local TTS or ElevenLabs streaming directly over WebRTC audio track.
The Verified PAI OS Software Stack
Every layer of PAI OS is built on audited, battle-tested open-source and local-first software. No proprietary lock-in.
- Hermes AgentPrimary conversational engine & multi-profile bot supervisor.
- Rakazo EnginePersistent autonomous browser automation with full DOM state.
- Paperclip PlatformBoard-level company task orchestration and review workflows.
- CrewAI & OpenClawRole-based subagent teams and cross-agent event routing.
- Ollama & llama.cppBare-metal GGUF tensor inference on unified RAM (Vulkan/Metal/CUDA).
- LiteLLM Unified ProxyResilient local model router with automatic rate-limit cascading.
- LM Studio RunnerLocal developer playground and one-click model quant evaluations.
- AirLLC AcceleratorLow-latency model serving optimization and caching layer.
- Cloudflare Email & HimalayaEdge-sealed X25519 inbound email with local CLI terminal IMAP/SMTP.
- Telegram Bot BridgeDirect local Telegram bot handling mobile prompts and alerts.
- WhatsApp & iMessageBaileys web bridge and local BlueBubbles / AppleScript gateway.
- Signal & MatrixZero-trust end-to-end encrypted messaging connectors.
- SQLite-vec WALDeterministic semantic vector embeddings stored on local disk.
- Tailscale MeshWireGuard peer-to-peer overlay network with zero WAN port forwarding.
- Local Cloud (Seafile)Self-hosted private document synchronization across all user devices.
- LUKS2 + TPM2Hardware-bound full disk encryption protecting data at rest.
Omni-Channel Ingress & Local Cloud
Interact with your assistant through whatever tools you already use every day. PAI routes each channel according to strict cryptographic boundaries.
Cloudflare Email + Himalaya
Inbound emails are sealed with ChaCha20-Poly1305 at the Cloudflare edge worker before transit. PAI unseals them locally and indexes them into your private semantic memory.
Telegram, WhatsApp & iMessage
Run dedicated chat bots directly on your box. Telegram long-polling connects outbound without open ports. Optional WhatsApp (Baileys) and iMessage (BlueBubbles) bridges keep conversations in sync.
Seafile Cloud & SQLite-vec
Full personal cloud syncing powered by self-hosted Seafile. Context, knowledge, and conversation embeddings live in an in-process SQLite-vec WAL database on high-speed NVMe storage.
Engineered for Every Workload
From compact fanless gateways to dual-slot eGPU workstation powerhouses, PAI hardware is purpose-built for high-throughput local inference.
| Model | Processor & Memory | Model Capacity | Expansion & I/O | Launch Price |
|---|---|---|---|---|
| PAI Pro 128Flagship Workstation | AMD Ryzen 9 7940HS 128 GB LPDDR5X (7500 MT/s) | 70B Quantized Models Full Mixtral 8x22B | Dual 2.5GbE • OCuLink (64Gbps) PCIe Gen4 NVMe • GaN 100W | $1,199 $2,999 |
| PAI Starter 64 / 32Balanced Home Server | AMD Ryzen 7 7840HS 64 GB or 32 GB Expandable | 14B – 32B Dense Models DeepSeek R1 Distill 14B | 2.5GbE • USB4 40Gbps M.2 NVMe • GaN 65W | $699 $1,499 |
| PAI EdgeCompact Gateway | Quad-Core Low Power 16 GB Unified Memory | 7B – 8B Fast Quant Models Llama 3.1 8B Instant | Dual 1GbE • Fanless Ultra-quiet 15W TDP | $399 $799 |
| PAI GPU DockOCuLink Accelerator | OCuLink SFF-8611 PCIe 4.0 x4 750W Titanium GaN PSU | Supports RTX 4090 / 5090 Zero Bottleneck 64 Gbps | Dual-Slot Full Length Tool-free Magnetic Enclosure | $449 $899 |
| PAI OSSoftware Image Only | Any x86-64 Hardware Minimum 16 GB RAM | Determined by host hardware Automatic model selection | Flashable USB Image Atomic bootc dual-slot updates | $59 $149 |
Ready to own your private intelligence?
Lock in your priority founder allocation with up to 60% launch discount on hardware workstations, or download PAI OS to turn your existing hardware into a sovereign AI server.